Data Engineer Resume Example (2026)
By FindAJobAI team Updated How we built this page
Data engineering ads are unusually consistent: SQL, Python, an orchestrator, a warehouse, and increasingly data quality and streaming. A data engineer resume should name each of those as you used them, with data volumes, refresh times and the people who relied on the data.
The example below is a data engineer with six years, who started as an analyst automating reports and now runs batch and streaming pipelines for a grocery retailer. Each bullet pairs a tool with the volume it handled or the problem it solved.
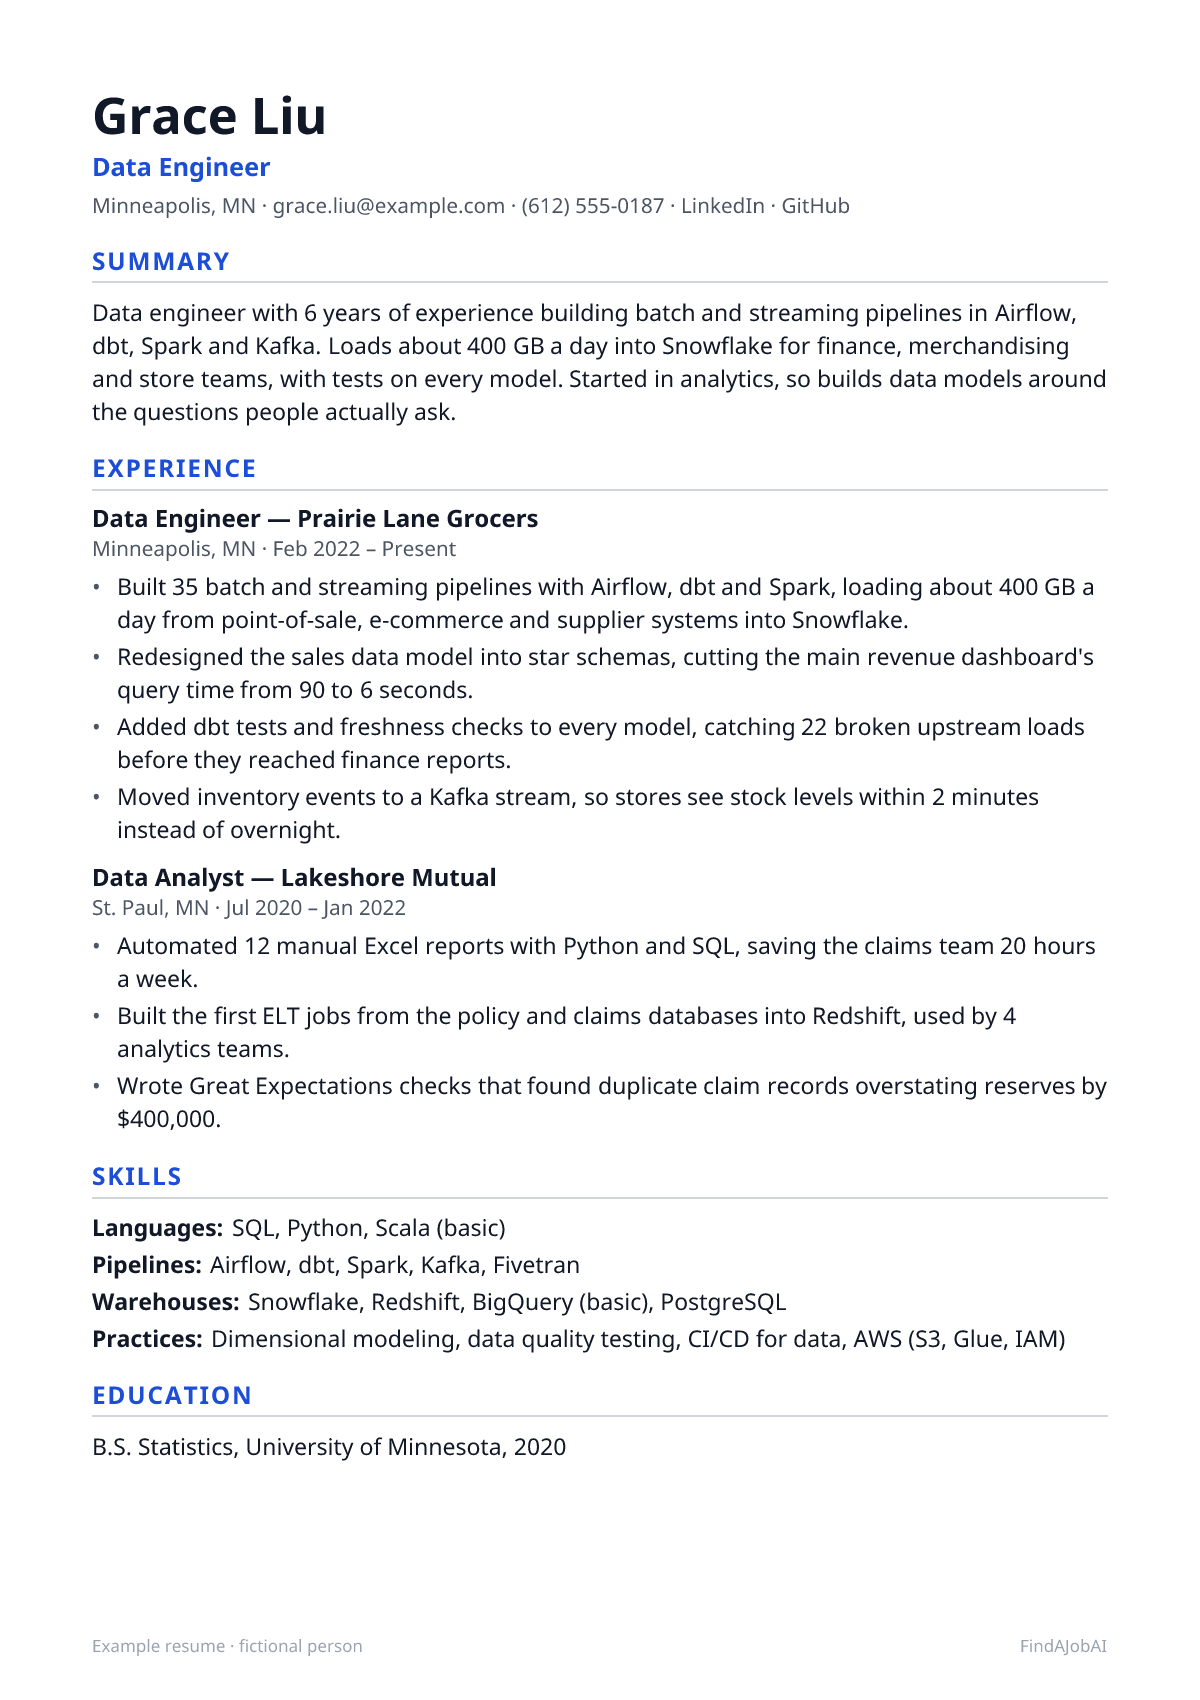
Data Engineer resume template
This example as a one-page template: one column, standard headings and plain text, the format applicant tracking systems read most reliably.
After you sign up, Create my CV builds your own resume in this same one-column layout, from your real experience.
Mid-level data engineer resume example
A complete one-page example for a fictional data engineer: every bullet pairs an action with what changed because of it.
Example resume · fictional person
Summary
Data engineer with 6 years of experience building batch and streaming pipelines in Airflow, dbt, Spark and Kafka. Loads about 400 GB a day into Snowflake for finance, merchandising and store teams, with tests on every model. Started in analytics, so builds data models around the questions people actually ask.
Experience
Data Engineer, Prairie Lane Grocers
Minneapolis, MN · Feb 2022 – Present
- Built 35 batch and streaming pipelines with Airflow, dbt and Spark, loading about 400 GB a day from point-of-sale, e-commerce and supplier systems into Snowflake.
- Redesigned the sales data model into star schemas, cutting the main revenue dashboard's query time from 90 to 6 seconds.
- Added dbt tests and freshness checks to every model, catching 22 broken upstream loads before they reached finance reports.
- Moved inventory events to a Kafka stream, so stores see stock levels within 2 minutes instead of overnight.
Data Analyst, Lakeshore Mutual
St. Paul, MN · Jul 2020 – Jan 2022
- Automated 12 manual Excel reports with Python and SQL, saving the claims team 20 hours a week.
- Built the first ELT jobs from the policy and claims databases into Redshift, used by 4 analytics teams.
- Wrote Great Expectations checks that found duplicate claim records overstating reserves by $400,000.
Skills
- Languages: SQL, Python, Scala (basic)
- Pipelines: Airflow, dbt, Spark, Kafka, Fivetran
- Warehouses: Snowflake, Redshift, BigQuery (basic), PostgreSQL
- Practices: Dimensional modeling, data quality testing, CI/CD for data, AWS (S3, Glue, IAM)
Education
- B.S. Statistics, University of Minnesota, 2020
Fictional example by the FindAJobAI team: the person, employers and numbers are invented. Keep the structure; use your own work and numbers you can explain in an interview.
Entry-level data engineer resume example
A junior engineer ten months into a first data job, with an internship before it. Each bullet names the tool with what it loaded and how often, which matters more at this stage than a long Skills list, and one project shows work outside the day job.
Entry-level example resume · fictional person
Summary
Junior data engineer with a B.S. in Computer Science and 10 months on a data platform team, writing Airflow DAGs and dbt models over a BigQuery warehouse. Comfortable in SQL and Python, careful with tests and documentation, and keen to work on streaming and data quality.
Experience
Junior Data Engineer, Badger State Health Plans
Madison, WI · Jan 2026 – Present
- Wrote 14 Airflow DAGs that load claims and enrollment files from 6 vendors into BigQuery, each with retries and Slack alerts on failure.
- Converted 20 legacy SQL scripts into tested, documented dbt models, so analysts can trace every column back to its source.
- Cut the daily membership load from 50 to 12 minutes by switching 3 full-refresh models to incremental ones.
Data Engineering Intern, Lakeview Logistics
Milwaukee, WI · Jun 2025 – Aug 2025
- Built a Python job that pulls tracking data from 3 carrier APIs into PostgreSQL every 15 minutes for the customer service dashboard.
- Added schema validation that rejected 2,300 malformed records in the first month instead of letting them break reports.
Skills
- Languages: Python, SQL, Bash
- Data tools: Airflow, dbt, BigQuery, PostgreSQL, Docker
- Practices: Git and code review, CI with GitHub Actions, data testing, incremental models
Projects
- Grid demand and weather pipeline (Airflow, dbt, DuckDB): loads hourly electricity demand and weather data for 12 states, with tests on every model and a public dashboard.
Education
- B.S. Computer Science, University of Wisconsin–Madison, 2025
Senior data engineer resume example
A platform lead twelve years in. The bullets are about the platform rather than one pipeline: who depends on it, what it costs, and how it keeps bad data away from them. The migration carries its scale, its timeline and the risk it avoided.
Senior example resume · fictional person
Monique Dubois
Data Platform Lead
Seattle, WA · [email protected] · (206) 555-0102 · LinkedIn · GitHub
Summary
Data engineer with 12 years in data platforms for payments and retail, leading a platform team of 5. Designed a lakehouse on Databricks and Delta Lake that serves 400 analysts and 20 production models, cut infrastructure costs by $1.1M a year, and introduced the data contracts that ended most breaking schema changes.
Experience
Data Platform Lead, Cascade Ledger
Seattle, WA · Apr 2021 – Present
- Lead 5 data engineers running a Databricks and Delta Lake lakehouse that processes 3 TB a day for finance, risk and product teams.
- Introduced data contracts with schema checks in CI for 12 producing services, cutting breaking upstream changes from 9 a quarter to 1.
- Moved 800 batch jobs off a legacy Hadoop cluster in 9 months with no missed regulatory report, saving $1.1M a year.
- Built the Kafka and Spark Structured Streaming layer that feeds fraud scoring within 5 seconds at 4,000 events a second.
Senior Data Engineer, Evergreen Market
Bellevue, WA · Mar 2017 – Mar 2021
- Designed the Snowflake warehouse and dbt project for an online grocer as it grew from 30 to 600 models, each with tests and a named owner.
- Replaced nightly database dumps with Debezium change data capture from 40 PostgreSQL tables, keeping data under 10 minutes old.
- Set up cost dashboards and auto-suspend rules that cut Snowflake spend by a quarter.
Data Engineer, Pacific Rim Freight
Tacoma, WA · Jun 2014 – Feb 2017
- Wrote Python ETL jobs that loaded shipment and invoice data into Redshift for 50 analysts.
- Replaced cron scripts with the company's first Airflow deployment, cutting failed nightly loads from 6 a month to 1.
Skills
- Platforms: Databricks, Delta Lake, Snowflake, Kafka, Spark
- Pipelines and modeling: Airflow, dbt, Debezium, data contracts, dimensional modeling
- Cloud and code: AWS, Terraform, Python, Scala, SQL
- Leadership: Platform roadmaps, hiring, design reviews, cost management
Certifications
- Databricks Certified Data Engineer Professional, 2023
Education
- M.S. Computer Science, University of Washington, 2014
How to write a data engineer resume
Five steps, in the order a recruiter reads the page. The format around them stays plain for every job: one column, standard headings, newest role first.
Header: name, target title and links
Put “Data Engineer” on the title line, plus GitHub if it holds a real pipeline. If your title was ETL developer, BI engineer or analytics engineer, keep it on the role and use the common title in the header.
Summary: what you do and your best proof
Name your core stack in one line (language, orchestrator, warehouse, processing engine), then the scale: data per day, pipelines owned, how fresh the data is and who relies on it.
Experience: newest first, a result in every bullet
Write each bullet as a system plus a number: what you built or fixed, with which tools, and the volume, runtime, cost or freshness that changed. Include the incidents you prevented; reliability is half the job.
Skills: grouped, in the ad's words
Separate languages, orchestration, warehouses, streaming and cloud. Data engineering ads usually ask for one of each, and grouped lines let a recruiter tick them off in seconds.
Education and certifications
A computer science, statistics or engineering degree goes last with its year. Cloud data certifications (Google Professional Data Engineer, Databricks, AWS) get their own section if you hold them.
Skills to put on a data engineer resume
Hard skills are the tools and methods of the job; soft skills are how you work with people. Each comes with one way to prove it, because a skill named only in a list counts for little. Add the ones you really have.
Hard skills
- SQL
- Show modeling or tuning at scale, such as a rewrite that cut a nightly run from hours to minutes.
- Python
- Name what you wrote in it (loaders, API clients, tests) and how much data it moves.
- Airflow
- Give the number of DAGs you own, their schedules and how failures reach you.
- dbt
- Count your models and tests, and say which teams query them.
- Spark
- Pair it with the data volume and the runtime before and after your change.
- Kafka
- Give events per second, end-to-end latency and what consumes the stream.
- Snowflake or BigQuery
- Name the warehouse and one cost or speed improvement you made in it.
- Data modeling
- Mention star schemas, data vault or a metrics layer and the questions it made easy to answer.
- Data quality testing
- Show the tests, freshness checks or contracts you added and the bad loads they stopped.
- Cloud data services
- List the services you used for data (S3, Glue, Dataflow, Data Factory) rather than the whole catalog.
- CI/CD for data
- Say how pipeline changes are reviewed, tested and deployed in your team.
- Change data capture
- Name the tool (Debezium, Fivetran) and how fresh the replicated data stays.
Soft skills
- Ownership
- Describe a pipeline you run end to end, including what you do when it breaks at night.
- Working with data users
- Show a requirement you clarified with analysts before building, and the rework it saved.
- Documentation
- Mention lineage, a data catalog or runbooks you keep current, and who relies on them.
- Prioritization
- Explain how you chose between new sources, fixes and cost work in one quarter.
- Mentoring
- Count the engineers or analysts you coached in SQL, dbt or code review.
- Problem-solving
- Tell one incident from symptom to root cause and permanent fix in a single bullet.
- Cost awareness
- Put a dollar figure on a warehouse or cluster saving you made.
What employers ask for in data engineer job ads
The skills named most often in the 468 newest data engineer job ads we track (out of 2,741 live postings), as the share of ads that mention each:
- 1SQL80%
- 2Python79%
- 3ETL75%
- 4Data modeling51%
- 5Data quality50%
- 6AWS47%
- 7Apache Spark44%
- 8CI/CD44%
Add only the ones you really have, in Skills and in a bullet that shows how you used them. The full list is on the Data Engineer resume keywords page.
From live job ads · computed November 2, 2026 · refreshed daily
Data Engineer resume bullet examples: weak vs strong
The same work, written two ways. The strong version names the tool, the scope and a result; the numbers are examples, yours must be real.
Weak: Built data pipelines.
Strong: Built an Airflow pipeline that ingests 2,000 supplier files a day, validates them and loads Snowflake by 6 a.m. for the buying team's morning review.
Volume, tools and the deadline the business cares about.
Weak: Worked with SQL and Python.
Strong: Rewrote a 1,200-line stored procedure as 14 tested dbt models, cutting the nightly run from 3 hours to 25 minutes.
Skills shown in a concrete refactor with numbers.
Weak: Improved data quality.
Strong: Added uniqueness and referential tests to 180 dbt models with Slack alerts on failure, so bad loads are fixed before analysts start work.
Quality as a system, with coverage and response.
Weak: Optimized queries.
Strong: Clustered the 4-billion-row events table and pruned unused columns, cutting Snowflake compute costs by $6,000 a month.
Warehouse tuning tied to cost, which data leaders track.
Weak: Supported the analytics team.
Strong: Built a metrics layer in dbt with 40 defined KPIs, ending conflicting revenue numbers across 3 departments.
Shows the business impact of data modeling.
Weak: Experience with streaming data.
Strong: Built a Kafka and Spark Structured Streaming job that flags payment anomalies within 30 seconds at 1,500 events a second.
A streaming claim backed by latency and throughput.
15 more data engineer resume bullet examples
Grouped by area of the job, so you can find the ones closest to your work. Keep the shape (action, scope, result) and replace the invented numbers with your own.
Pipelines and orchestration
- Replaced 45 cron scripts with Airflow DAGs that have retries, SLAs and owners, ending the silent load failures that had hit about 8 times a month.
- Built an ingestion framework that adds a new SaaS source through a config file instead of code, bringing 12 sources online in a quarter.
- Backfilled 5 years of order history, 2.4 billion rows, in 3 days with partitioned Spark jobs and no downtime for reports.
- Cut the critical overnight run from 5 hours to 70 minutes by running independent tasks in parallel and removing 3 redundant joins.
Warehouse modeling and performance
- Modeled subscription events into a dbt fact table with daily snapshots, giving finance its first reliable monthly recurring revenue figure.
- Partitioned and clustered the 9 TB clickstream table in BigQuery, cutting the cost of the 20 heaviest queries by $4,000 a month.
- Built slowly changing dimensions for customers and products, so analysts can report any figure as it stood on a past date.
Data quality and reliability
- Added freshness, volume and schema tests to 250 tables with alerts routed to owning teams, cutting data incidents reported by users by two-thirds.
- Wrote a daily reconciliation between warehouse revenue and the billing system that caught a $70,000 discrepancy within a day.
- Ran the on-call rotation for 60 pipelines and wrote runbooks that cut median recovery time from 3 hours to 40 minutes.
- Masked personal data in 30 tables with column-level policies, passing a privacy audit with no findings.
Streaming and platform
- Built a Kafka Connect pipeline that streams app events into Snowflake within 2 minutes at 6,000 events a second.
- Moved the data platform's infrastructure to Terraform, so a full development copy comes up in 20 minutes.
- Set up CI for the dbt project that builds only changed models, cutting pull-request checks from 35 to 6 minutes.
- Agreed data contracts with 5 product teams and added schema checks to their deploys, so breaking changes fail before release.
Data Engineer resume summary examples
Two or three lines on what you do and your strongest proof. Start from the one closest to your level and use your own facts.
Data engineer with a statistics degree and a year as an analyst automating SQL and Python reports. Built a portfolio pipeline with Airflow, dbt and BigQuery on public transit data. Strong in SQL and ready for production pipelines.
Data engineer with 5 years of experience building Airflow, dbt and Snowflake pipelines for e-commerce. Owns the core sales and inventory models used by 60 analysts, with tested, documented data delivered by 6 a.m. daily.
Senior data engineer with 10 years of experience leading data platform work for a fintech processing 50 million transactions a month. Designed the lakehouse on Databricks, the streaming layer on Kafka and the data contracts between product and analytics teams.
Common data engineer resume mistakes
Each one is easy to make and quick to fix before you apply.
A wall of tools with no scale
Forty logos don't show whether you ran any of them in production. Attach a volume, schedule or latency to each tool in a bullet.
Pipelines described without their users
A pipeline matters because someone reads its output. Say who used the data and what broke for them when it was late.
Leaving out reliability work
Tests, alerts, on-call and backfills separate an engineer from a script writer. Give them their own bullets, with the incidents they prevented.
Writing an analyst resume for an engineering job
If you're moving from analytics, lead with the engineering parts of that job: scheduled jobs, version control, tests and deployments, not the dashboards.
Ignoring cost
Warehouse and cluster bills worry every data leader. One bullet with a cost cut and how you achieved it earns its place.
ATS tips for a data engineer resume
Applicant tracking systems turn your file into text that recruiters search, mostly for the skills and titles in the ad. They rarely reject a resume on their own; one that parses badly or misses the ad's words just doesn't come up.
- Name the warehouse (Snowflake, BigQuery, Redshift, Databricks) and the orchestrator (Airflow, Dagster, Prefect) you used; data engineering ads usually ask for one of each.
- Give data volumes: rows or GB per day, tables, pipelines and refresh times.
- List tools (dbt, Spark) and modeling methods (dimensional modeling, data vault) separately; recruiters search for both.
- Show reliability with tests, alerting and freshness targets; ads increasingly ask for data quality by name.
- Keep SQL visible in Skills and in bullets. It's easy to take for granted and leave out.
For the format itself, run the free ATS resume checklist.
Everything for Data Engineers
- Data Engineer jobs2,741 open roles, updated hourly
- Data Engineer salary in the United StatesAdvertised pay in real job ads
- Data Engineer cover letter examplesThree example letters and a short email version
- Data Engineer interview questions30 questions with sample answers
- Data Engineer resume keywordsThe skills job ads ask for most
- Data Engineer job descriptionDuties, skills and requirements
- How to tailor your resume without lying
Other resume examples
Data Engineer resume FAQ
What should a data engineer resume include?
Your languages (SQL, Python), orchestrator, warehouse, transformation tool and any streaming work, each shown in bullets with data volumes, refresh times and who used the data.
How do I move from data analyst to data engineer?
Show the engineering side of your analyst work: automated pipelines, scheduled jobs, version control and tests. A portfolio project with Airflow or dbt loading a warehouse closes much of the gap.
Do data engineers need cloud certifications?
Not usually, but a cloud data certification from Google, AWS, Databricks or Snowflake can help when you're changing stacks. Production pipeline experience counts for more.
How we built this page
The FindAJobAI team wrote the three example resumes, the bullets, the skills and the advice for data engineer roles. The people, employers and numbers in the examples are invented; the structure, the tools and the way each bullet is built are the parts to copy.
The live skills section is based on 468 data engineer job ads analysed, the newest we track, with the same deterministic skill matcher as our in-demand skills report: no AI model reads the postings. It was last computed on November 2, 2026 and refreshes daily.
Last reviewed on November 1, 2026.